
New Term Radar
FreeNot checkedDaily radar for new AI terms: names of new models, products and repos, caught on X, Hugging Face, GitHub and sitemaps before keyword tools list them.

About
Daily radar for new AI terms: names of new models, products and repos, caught on X, Hugging Face, GitHub and sitemaps before keyword tools list them.
README

new-term-radar
Catch the names AI people are about to search for, the day they appear, before keyword tools list them.
PyPI Python License: MIT Stars Forks Downloads Last commit
MCP Registry Tessl registry LobeHub Security-graded by Agent Skills Hub Cursor Directory ClawHub skills.sh
⭐ 700+ stars on its first day, 1,000 in just over three · on PyPI, the official MCP Registry, Cursor Directory, LobeHub, Tessl, ClawHub and skills.sh
Quick start · What it reads · The keyword table · Agents and MCP · config.json · 中文说明
A daily report of the names that are starting to surge in AI: new models, products, tools and repos, caught where they are said first, before they show up in keyword tools.
Built for people who make pages, posts or products around new terms: SEO for AI tool sites, newsletters, directories, anyone who wants to know about "Strata" or "Seedance" the day it appears and not two weeks later.
Why
A new name leaves a trail, in this order:
- A lab or a well-followed account says it on X; a model enters Hugging Face's trending list.
- One GitHub repo takes off on its own.
- Directories and competitors add pages for it; someone registers a domain for it and the site starts to rank.
- Your own site gets its first search impressions for it.
- Google Trends shows the curve, days or weeks later.
Keyword tools read step 5. This radar reads steps 1 to 4 every day and uses step 5 only to check itself.
One example it was built around: Niko1221/Strata was created on 2026-09-24 and had 7,700 stars nine days later. People were searching "niko strata" from 9/26, while no second repo carried the name and no keyword tool listed it. A single repo gaining 800 stars a day is the whole signal, and it is public.
What it reads
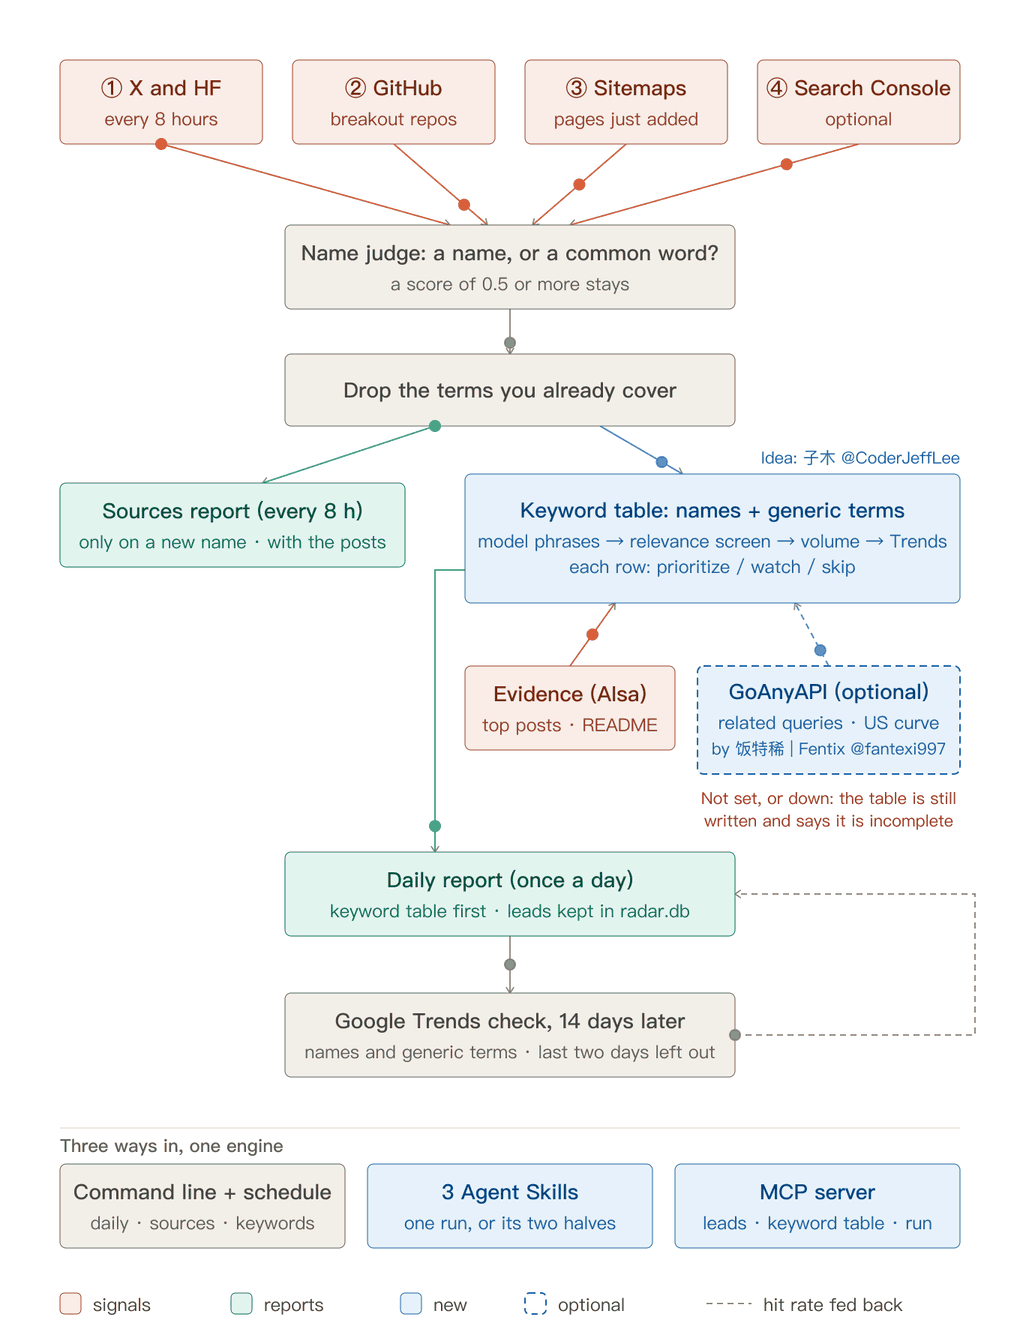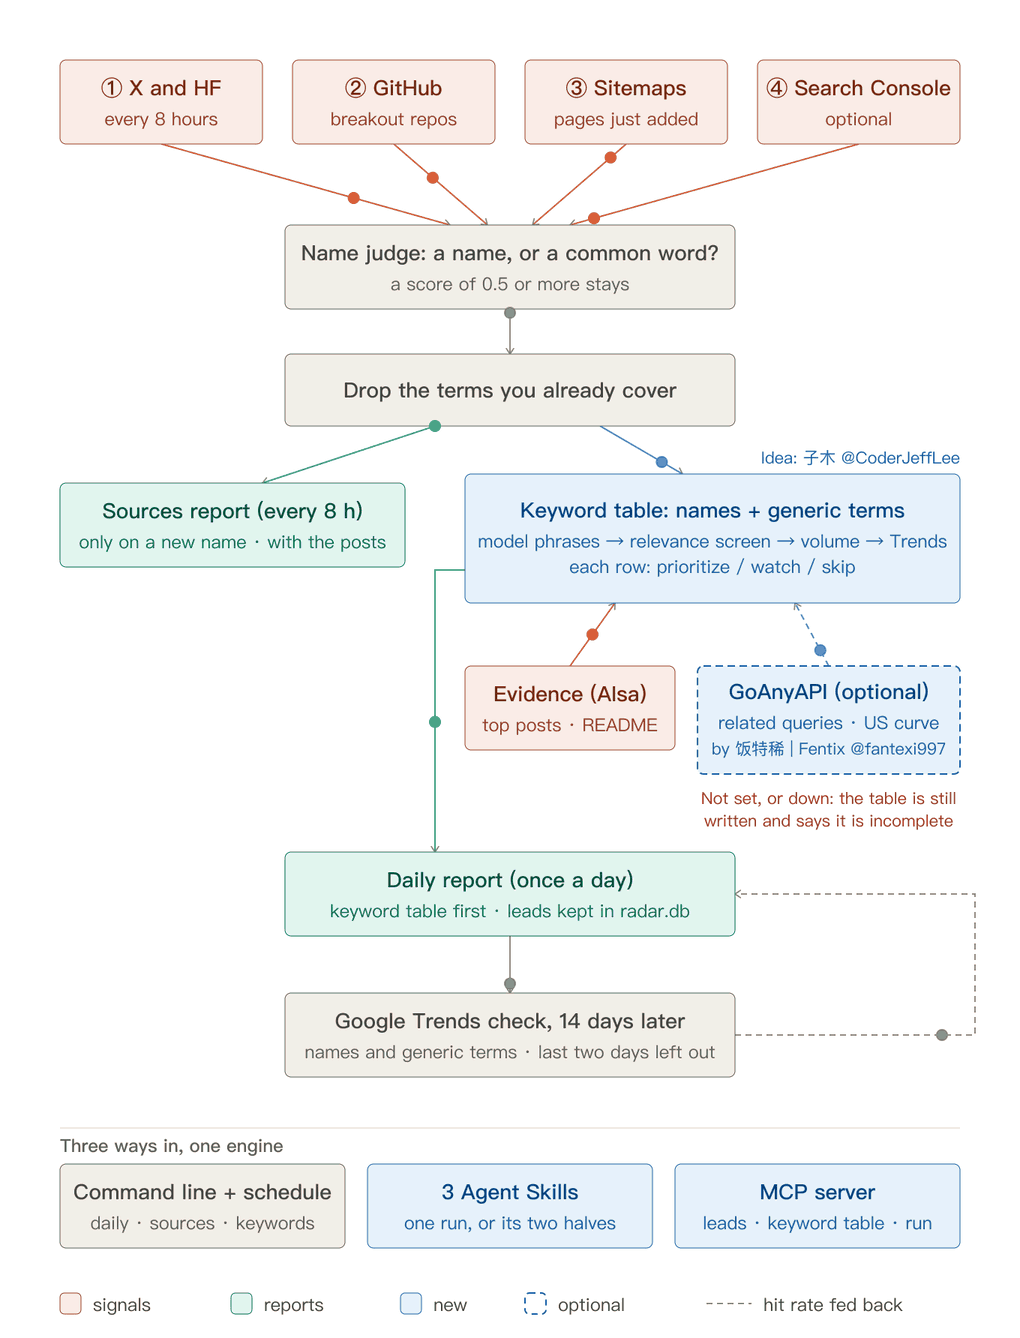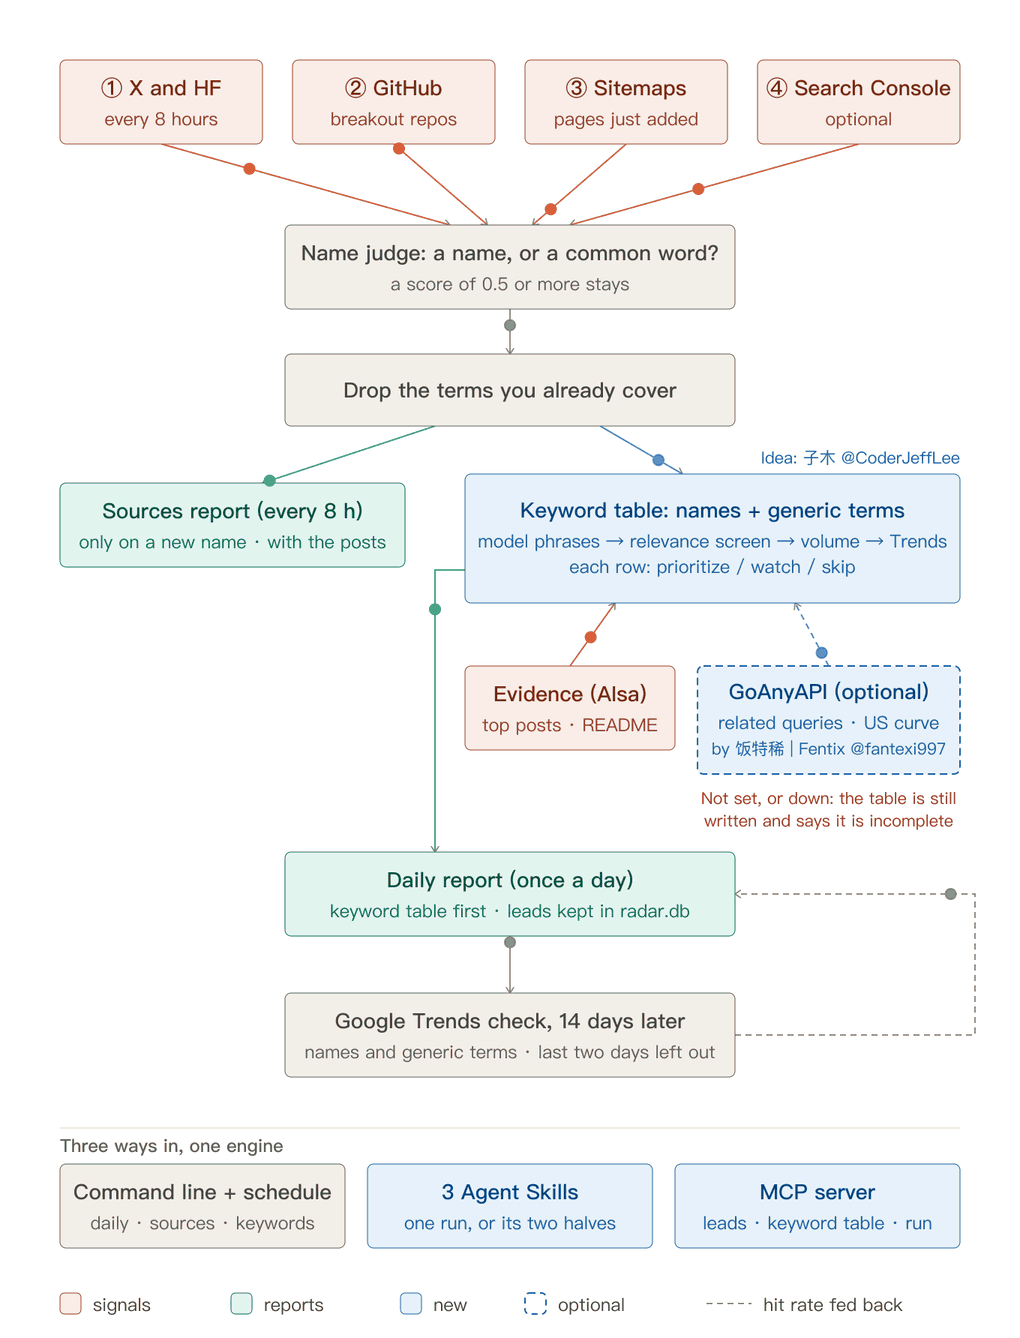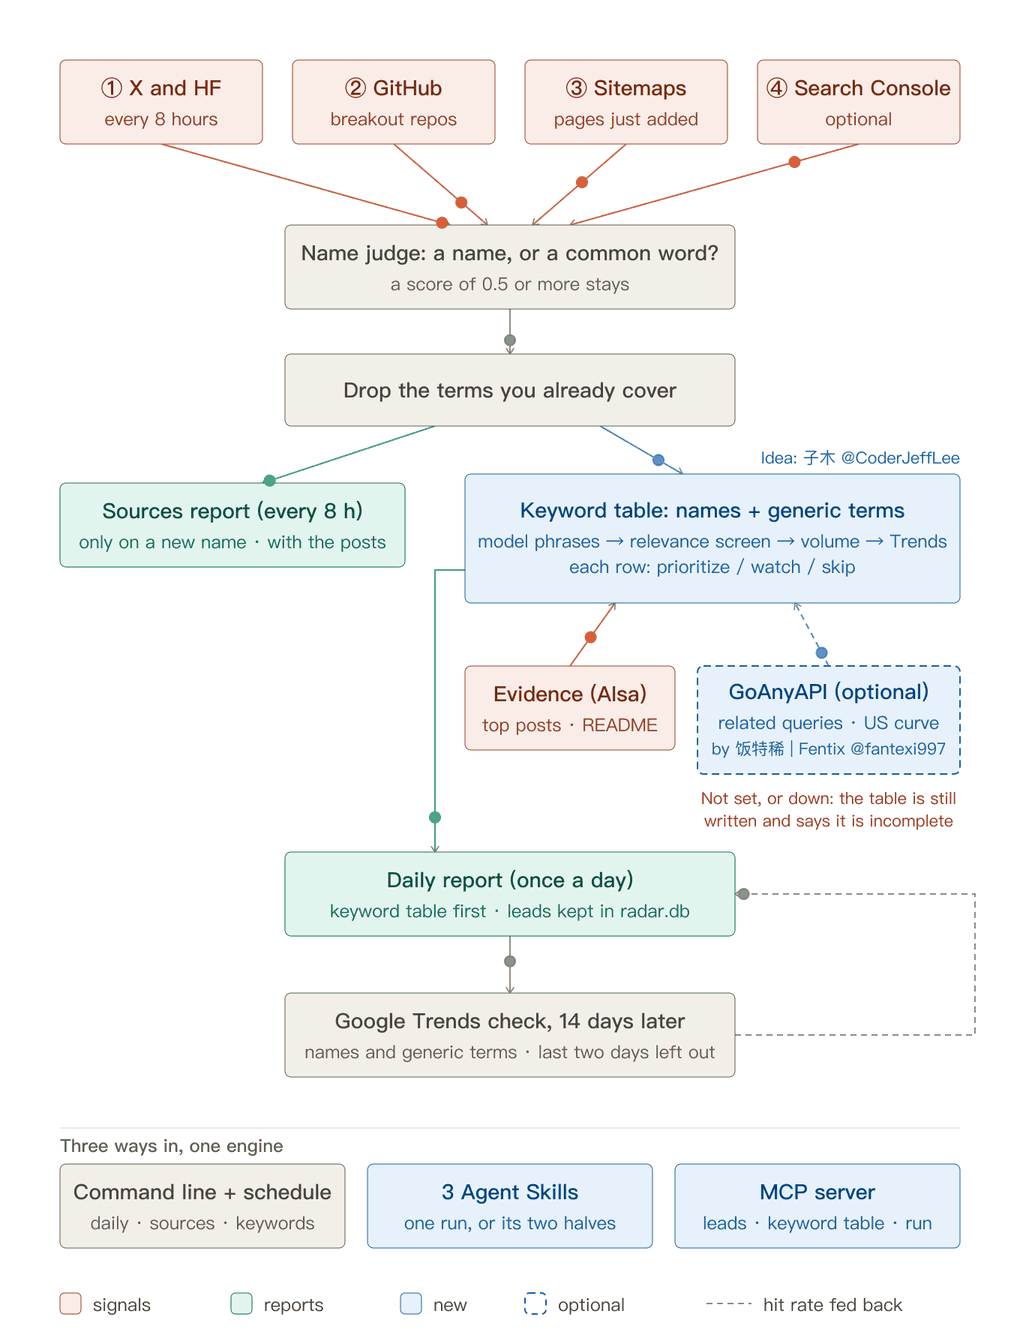
Purple, tagged NEW: what 0.3 to 0.5 added (⑥ revenue, ⑦ Reddit asks, ⑧ sellers, the page-one check, the format and ⚡ marks, the pains command).
| Signal | What it catches | Needs | Cost |
|---|---|---|---|
| ① X | Names the accounts in your list used for the first time in 60 days | AIsa key | $0.003 per account per run |
| ① Hugging Face | Models and Spaces (the demos people try) new to the trending top 50; quantised copies and a model's own demo grouped under the base name | nothing | free |
| ② GitHub breakout | A repo under 14 days old averaging 200+ stars a day, or +400 since yesterday; adds the search variants people use ("niko strata") | nothing (a GitHub token raises the rate limit) | free |
| ③ Sitemaps | Words that several new URLs on a site share and its older URLs rarely carried. The example config watches eight AI tool directories (toolify, aixploria, ai-bot.cn, opentools, dang.ai, clipfly, aitoptools, futurepedia) and four MCP and skill directories | the sitemaps you list | free |
| ③ New sites | Domains registered and first indexed in the last 90 days that already rank for 20+ keywords | AIsa key | about $0.13 per query, weekly |
| ⑦ Asks | What people ask for on Reddit ("is there an AI tool that…", twelve phrasings): a model keeps the requests and complaints an AI tool could answer and writes each job as people would search it; jobs with searches get the page-one check | AIsa key | about $0.12 a week |
| ⑧ Sellers | Sites that just put up their first payment link (Stripe Payment Links, Polar, Lemon Squeezy, Gumroad, Creem), from the public link graph with the day each site first linked; new pages of old sellers, platform pages and forum threads left out; the site's own description goes to the keyword table | AIsa key; GoAnyAPI optional, for visits | about $0.40 a week |
| ⑥ Revenue | Products people pay for, from TrustMRR's verified revenue: the fastest growing ($500+ in 30 days) and the newest listings; one at $0 last time and earning now is called out first. Its own description goes to the keyword table as evidence | TrustMRR key | free, 6 requests, weekly |
| ④ Search Console | Queries your site got impressions for, for the first time (fresh data) | your own Google token | free |
| ⑤ Review | Each lead checked in Google Trends 14 days later, against its own baseline; hit rate and days ahead per signal | AIsa key | $0.0012 per search variant |
| Keyword table | For the day's new names: the generic search terms behind them (what people do with the new thing), each sized, checked for room on page one, and given a decision | AIsa key; GoAnyAPI key optional | about $0.18 a day for 5 names, $0.30 with GoAnyAPI |
| Name judge | A small model scores every term: the name of one specific thing, or a common word? | AIsa key | a fraction of a cent per run |
Prices are what AIsa charged in October 2026. With the example config (35 X accounts read three times a day, the keyword table for 5 names a day) a month costs about $15: $10 for the X reads, $5 for the keyword table. Read fewer accounts, or read them once a day, and it drops in proportion.
The keyword table
A name is half of what you need. "SynthID Detector" has a short life as a keyword and belongs to Google; the job it does, "ai image detector", is what people keep searching, and nobody owns it. Each day the radar reads the new names once more and writes one table with both:
| Keyword | Type | Behind | New? | Est. searches/day | Started rising | Peak vs gpts | Peak day | Last 7 days vs the 7 before | Now | Page one | Decision |
| **photocraft** 🖼 | name | — | yes | 12747 | 2026-10-05 | 97 vs 3.1 | 2026-10-09 | — | still rising | — | **prioritize** |
| **claude haiku 5.5** | name | — | yes | 1863 | 2026-10-07 | 100 vs 23.7 | 2026-10-08 | ×6.0 | still rising | — | **prioritize** |
| **ai image detector** 🖼 | generic | synthid detector | no | 2537 | — | 87 vs 31.6 | 2026-10-04 | ×1.2 | flat | — | watch |
| **photoshop alternative** ⚠ | generic | photocraft | no | 244 | — | 61 vs 61.7 | 2026-10-08 | ×1.8 | flat | — | skip |
(a real run, 2026-10-12, shortened; the Page one column came later, see below)
How it is made (radar/usecases.py):
- Evidence: the most-liked posts that mention the name (X advanced search) and, for a repository, its README.
- Phrases: a model reads the evidence and writes the keyword an ordinary person would type for each job it sees people doing, with a quote that backs it. A phrase built on another product's name ("photoshop alternative") is kept and marked ⚠: demand often hangs on the incumbent, and whether to use someone's brand is your call. With a GoAnyAPI key (optional, below) the radar also takes Google Trends' related queries for the name: what people really searched together with it. For SynthID Detector that gave "ai photo detector", "google ai detector" and "ai detector"; these rows carry 🔎. Queries that hold the name are listed as its long-tails ("photocraft download", "nano banana 2.1 vs pro"). Queries that are themselves the names of other rising things ("gpt image 2.5" beside "nano banana 2.1") are kept as leads of their own.
- Screen: a second call scores how well the name answers each phrase, marks brands, and spots the names of other things; the loosely related ones are dropped. For Claude Haiku 5.5 it dropped all six proposed ("ai coding assistant", "github copilot alternative"); for SynthID Detector it kept all five.
- Volume: Google Ads monthly searches for the rest, one batch call. Phrases under
min_volumeare dropped; most are. - Trends, twice per row: the term alone gives the shape (new or not, the day it started rising, the peak, the last week against the week before, what it is doing now); the term beside a benchmark keyword (
gptsby default) gives the size. - Page one, for the rows that would be acted on (eight at most): Google's first page (about $0.002 a keyword), the rating of each site on it (GoAnyAPI, $0.002 a site, kept 30 days) and the keyword difficulty ($0.012 a call). With a GoAnyAPI key also who already builds for the term and who pays for it: the pages Google holds with it in the title from the last month (
pages built) and the domains running Google ads on it (advertisers, from Ads transparency), $0.008 a row.open= three or more of the ten results sit on sites rated under 30, or difficulty under 20;crowded= none does and difficulty is 40 or more;mixedin between. Under the table it names the weakest site on page one, where a new page can get in, and what kinds of pages hold it (tools, lists, articles, videos, forums). Ads on the page mean someone pays for that click.
Searches a day are estimates. A generic term's come from its own Google Ads volume, moved to today along its own Trends curve. The benchmark is then sized from those terms, and a name, which has no volume data yet, is sized against the benchmark.
Decision: prioritize = rose in the last 30 days, still up, at least min_daily searches a day. watch = rose but smaller, too early to read, or flat with steady demand of that size. skip = fading, or flat and small. A prioritize whose page one is crowded becomes watch ↓: still rising, but page one belongs to strong sites. In a name's first week page one is still forming (news, the maker's own pages); the second reading three days later is the one to trust.
Marks: 🎬 video, 🎙 voice, 🖼 image says what the thing makes, the usual order of what visitors pay for (video > voice > image > text); leads of equal standing are sorted by it. ⚡ = a post with 1,000 or more likes walks through a manual workflow or rides a trend: a one-click tool nobody has built yet. Both come from keyword rules over the lead's own words and posts; on six known names (Nano Banana, Veo 3.1, Seedance 2.5, Claude Opus 5.5, ElevenLabs v4, Qwen Image 2.1) the format came out right for all six and ⚡ fired once, on a widely shared Opus 5.5 + Blender + Unreal walkthrough. Read the posts before acting on a mark.
Each name is read twice, the day it appears and three days later, because on announcement day the posts are announcements and no use shows yet. The generic terms are kept as leads and reviewed after 14 days like the names.
What to expect from it, from the first eight names we ran it on:
- The names rose; most generic terms did not, within five days. PhotoCraft, Claude Haiku 5.5 and SynthID Detector all climbed clearly. Of the generic terms behind them, one moved: "photoshop alternative" ran about 80% above its level in the US for five days after PhotoCraft appeared. The worldwide daily series the table reads showed almost nothing of it (2, 1, 1, 2, 4, 2); a US daily series from another source showed it plainly. So a flat reading from the worldwide series does not prove a term did not move. With a GoAnyAPI key the bigger rows are read from the one-country series instead, where a rise is 1.5 times the earlier level held for three days; the same run then shows "photoshop alternative" as
still rising (US). - The table's dependable use today is to tell you which existing demand a new thing serves and how big it is ("ai image detector", about 2,500 searches a day). Whether generic terms follow the names is what the 14-day review will show, and we have no result yet.
- For pure model releases (Claude Haiku 5.5, Nano Banana 2.1) the evidence was announcements and benchmarks, and the phrases proposed were weak ("ai coding assistant"). It works better for products and repositories that do one job.
- Google Trends' last two days are not settled. For unrelated terms they came back as 0 and then 100, which reads as a spike. Our first pass was fooled by exactly this; every reader in the code now drops those two days, and a rise must last two days to count.
- Google Ads volumes run about two months behind. Trends reads nothing reliable for terms under a few hundred searches a month.
When a source is missing or down
The table is still written, but it gets thinner, and it says which part is missing:
| What happens | What the table loses | The line it prints |
|---|---|---|
No GOANYAPI_API_KEY (the default) |
The 🔎 rows, each name's long-tails, the other names searched alongside, and the (US) readings. Phrases come from the model alone and every curve from the worldwide series, where a real move can read flat |
"Related queries are off: set GOANYAPI_API_KEY…" |
| GoAnyAPI's Trends is down (seen on its first day in use, 2026-10-12) | The same as having no key, for that run | "Related queries failed for: …" and "Country series failed, worldwide data used instead: …" |
| AIsa's post search fails for a name (timeouts seen twice on 2026-10-13) | That name's posts. A repository still has its README; a model or product without one is left with the related queries only, and with no GoAnyAPI key it gets no generic terms that day | "The post search failed; this run used READMEs and related queries only: …" |
| Neither posts nor a README for a name | Its generic terms; the name's own row stays | "No posts or README found for: …" |
| No lead that day is a thing with a name score of 0.8 or more | The whole table | "Nothing to read today…" |
| AIsa's search-volume or Trends lookup fails | The whole table: these two are not replaceable | the error, in place of the table |
A thin table is not a quiet day. Read the lines under it before you conclude that nothing moved.
Set "usecases": {"per_day": 0} or pass --skip usecases to turn it off.
⑥ Revenue: what people already pay for
A product that makes money proves the demand behind it. With TRUSTMRR_API_KEY set (from TrustMRR's developer dashboard), the radar reads once a week (revenue.weekday, Monday by default) the 30 fastest-growing products with at least min_revenue_usd ($500) in the last 30 days and the 30 newest listings, and keeps what it saw. The newest listings mostly earn next to nothing yet; they are read to record where they start, so a product at $0 last time that earns past the floor now is called out first. Hidden listings ("Anonymous startup") are left out, and a company's legal name gives way to its site's name ("Talent Tech Global Limited" is read as gptproto). Each product's own description goes to the keyword table as evidence, so the table reads the job people pay for, not only the brand. Growth above 1,000% reads "up from near $0": on the first run most of the fastest growers had started from almost nothing.
TrustMRR's API terms forbid republishing its data and building public SEO pages from it. Use the leads for your own research; do not publish the list.
⑦ Asks: demand said out loud
Once a week the radar searches Reddit for a dozen ways people ask for a tool ("is there an AI tool", "I wish there was a tool", "how do I automate", in asks.patterns), keeps the posts of the last week with a score of 2 or more, and has a small model sort them: a request, a complaint, a shared solution, or other. For requests and complaints an AI tool could answer, it writes the job the way a person would search it ("add b roll automatically", "convert slides to notes"). Jobs with at least 50 searches a month are listed with their posts and get the page-one check; each becomes a lead. Most asks are too specific to have searches yet: the first real week, 84 posts held 43 asks and only two had 50 searches a month ("best ai tool for research", from a 1,034-point r/PhD thread, and "best ai tool for coding"). So the best-scored of the others are listed too, as ideas rather than keywords. A month of posts read in a trial held a request for "an AI tool to convert PowerPoint lecture slides into notes", the same job a tool-site course uses as its worked example.
Posts are for your own research: quote them, do not republish them.
⑧ Sellers: who just started taking money
A product's first payment link says more than its launch post: someone built a thing and asked for money for it. whoismaking.money used to rank sites by the traffic they sent to Stripe's checkout (clickstream data; its last real page in the Internet Archive is from September 2025, and by March 2026 the domain served a parked page with a hidden redirect). The same kind of data is on sale through AIsa's Similarweb at about $6 for 20 rows: too dear to cover the long tail. Payment links are a cheap stand-in. They are ordinary links on the seller's own page, so the public link graph shows them with the day each first appeared. Stripe has 143,000 linking sites and Polar 1,900 (every link a payment link); for Lemon Squeezy, Gumroad and Creem only store checkouts, /l/ products and /payment/ pages count, since their other links point at their own marketing sites and, for Gumroad, at profile pages spam networks use.
Once a week the radar reads, for each platform, the newest 100 payment links and the newest 100 sites to link to it for the first time (about $0.06 a platform), keeps the links of those new sites, and lists the sellers with their visits (GoAnyAPI) and their own home-page title and description, which also go to the keyword table as evidence. The first real run put janitorai.com, framer.com, pub.dev, Flathub and an n8n forum thread on top: user pages on big platforms that link to someone's payment link. So the linking page must be the site's own home, pricing or product page, not a post, thread or listing; the site must rank 350 or lower on DataForSEO's 0 to 1,000 scale; and above 300,000 visits a month it counts as a platform. A small model then sorts the new sellers by kind from their own words (keyword rules when it cannot), and AI and software come first, then templates, courses and the rest; within a kind the busiest first. On the first sorted run all twelve listed were software (a live-captions app for the Mac, a chat-with-PDF tool, an AI writing app for macOS, an MCP catalog, a Japanese audit SaaS among them), where traffic alone had put a Blender add-on site, a recipe blog and a design gallery first. A payment link means the site sells, not that it sells well, and checkouts made by code at payment time are not seen.
A new link is not a new seller. A first version took the newest links for new sellers; on 2026-10-14 we checked them against the day each site first linked to the platform. A site that has sold for years puts the same link on every new page it makes (one carries its Stripe link on each of its well-permit pages), and two thirds of the 2,000 newest Stripe links came from such sites: of the 60 Stripe sellers that day's list showed, 17 had just started. So a seller is new by the day its site first linked to the platform (DataForSEO's referring domains), and the report says how many links came from sites that sold already.
History: every seller back to 2019
python -m radar history pull            # every site linking to the five platforms today: about $18
python -m radar history read            # their home-page titles and descriptions, free
python -m radar history sort            # their kind, by a small model: about $0.005 for 60 sites
python -m radar history --out sellers.csv
history pull reads every site that links to each platform today, one row per site with the day it first linked: DataForSEO's one-per-domain backlinks, oldest first, 1,000 a call ($0.06). On 2026-10-14 that day matched the referring-domain first-link day for all 1,704 Polar sites both lists name alike. It stops at --max-usd (default 20) and resumes where it stopped. history alone counts sellers per month, platform and kind; --out writes them all to a CSV. The rows are DataForSEO's: for research, not to republish.
How far back it goes, from the link graph's monthly count of sites linking for the first time (2026-10-14; one call per platform, $0.03):
| Platform | Counted from | Sites since 2019 | New sites a month, May to September 2026 | Linking today |
|---|---|---|---|---|
| Stripe | June 2021 (a few dozen a month before) | 306,000 | 6,500 to 8,200 (14,200 in June) | 143,000 |
| Gumroad | 2019 | 530,000 | 4,200 to 5,700, while 6,400 to 9,400 drop their links | 140,000 |
| Lemon Squeezy | 2023 | 34,000 | 600 to 1,100 | 18,000 |
| Polar | 2024 | 2,285 | 109 to 268 | 1,943 |
| Creem | 2025 | 1,708 | 74 to 268 | 1,449 |
Two cautions. In October 2023 Stripe's count jumped from 3,216 to 16,206, and new links from 1.2 million to 20 million the month after: the crawler grew, not the sellers. And a pull holds only sites that still link, so the older the month, the more of its sellers are missing. For Gumroad, Lemon Squeezy and Creem the monthly counts also include links to their own sites and to profiles; the pull keeps those apart (only payment links count as sellers).
⚡ What tutorial viewers ask for
For up to three leads a day marked ⚡ (a widely shared walkthrough of a manual workflow), the radar finds the top tutorial videos for the lead (GoAnyAPI), reads their comments (AIsa, $0.001 a page) and has the model pull out what viewers ask for: the steps they find too hard, the "can this be done in one click". That list is the one-click tool. It needs a GoAnyAPI key to find the videos.
Pain points: python -m radar pains "ai headshot"
What people complain about for a kind of tool, grouped into the gaps a new tool can fill:
- low-star Chrome Web Store reviews (1 to 3 stars) of the extensions Google shows for the keyword, or of the ones you name with
--extension ID(GoAnyAPI: 2 credits to find them, 3 a page of reviews); - Reddit posts that complain about the job or its tools ("{keyword} alternative", "{keyword} frustrating", ...; AIsa);
- comments under the top tutorial videos for the keyword (AIsa).
A model groups them into gaps (missing, too hard, quality, price, wants a tool), each with a count, an example and the phrase someone with that problem would search. About $0.05 a keyword. Counts are of what was read, not of the market.
What it cannot read: App Store, Google Play and Trustpilot reviews (DataForSEO serves them as tasks to post and fetch later, and AIsa runs synchronous calls only); There's An AI For That's request board (a Cloudflare challenge in front of every page; getting past it would be getting past their bot protection, so the radar does not); Facebook groups (Meta closed the Groups API in April 2024, and its research library is open to approved academic and nonprofit researchers only).
One key, and an optional second
Everything the radar needs goes through AIsa: X posts, Google Trends and domain data (DataForSEO behind it) and the models that judge names and propose phrases. One key, pay per call, no subscriptions to X's API or DataForSEO.
That link is a referral link: signing up through it supports this project. The radar works the same with a key from anywhere on aisa.one.
Optional: GOANYAPI_API_KEY (goanyapi.com) improves the keyword table in two ways, for about $0.07 a day: it adds Google Trends' related queries for each name, and it reads the curve of the names and the bigger generic terms (1,000 searches a month or more, eight rows at most) from 30 days of daily data for one country, settled to yesterday. Those rows show the country after "Now", as in still rising (US). Without the key the table is built from the model's phrases and the worldwide series alone. The service is young (first released in August 2026); in our tests calls took 20 to 55 seconds and about one in ten failed, so the radar tries twice, reports a failure in the table and carries on. That link is a referral link too.
Without an AIsa key the free signals still run (Hugging Face, GitHub, sitemaps, Search Console); the report then lists every term unsorted, because nothing judges which are names.
Quick start
Python 3.10 or newer. The radar uses only the standard library.
g